
A3 · Proposed ICLR 2027 Workshop
Auditing
AI Agents
Evidence, Evaluation,
and Accountability
What conclusions does the evidence support, and how can others check or challenge them?
Explore the proposed programFrom Agent Behavior to Checkable Claims
We bring together researchers who detect, diagnose, and test agent failures, and assess reliability and safety. Across benchmarks, monitors, and audits, we ask what the available evidence can establish.
What Was Recorded?
Execution traces, tool permissions, environment state, reasoning traces, and the consequences of missing or selected information.
What Does It Show?
Failure diagnosis, adversarial testing, measurement validity, uncertainty, and reliability when tasks, tools, or environments change.
Who Can Check It?
Independent assessment, access limits, conflicting conclusions, contestation, and evidence that a failure has been fixed.
A Day of Talks, Questions, and Shared Evidence
Proposed ProgramFour Complementary Perspectives
Deployed agent systems; ML evidence and monitoring; evaluating agent workflows; security and adversarial testing.
Research Talks and Poster Discussions
Methods, evaluations, negative results, re-analyses, and case studies from the community.
One Claim, Different Evidence
Assess a coding agent's claimed repair and revise your judgment as the audience chooses which evidence to reveal.
Which Claims Survive Independent Assessment?
Invited participants compare what can be concluded under restricted access and identify the next research questions.
The workshop day, detailed schedule, and talk durations will be finalized after acceptance.
The Evidence-Comparison Session
Would the Next Piece
Change Your Conclusion?
A planned exercise puts the audience in the evaluator's seat. A coding agent reports that it fixed a CSV parser. What would you need to believe the claim?
- 01 / Assess
Start with the Claim
Read the task, completion report, and reported tests. Record your verdict and confidence before the expert assessments.
- 02 / Reveal
Ask for More Evidence
Choose from code and test changes, execution traces, and permissions. Update your judgment as the record expands.
- 03 / Replay
Compare with an Independent Check
See a replay with unchanged tests and held-out cases. Discuss what remains unresolved, even when the tests pass.
Voluntary audience judgments make changes in verdict and confidence visible. Agreement alone does not establish correctness.
Invited Speakers
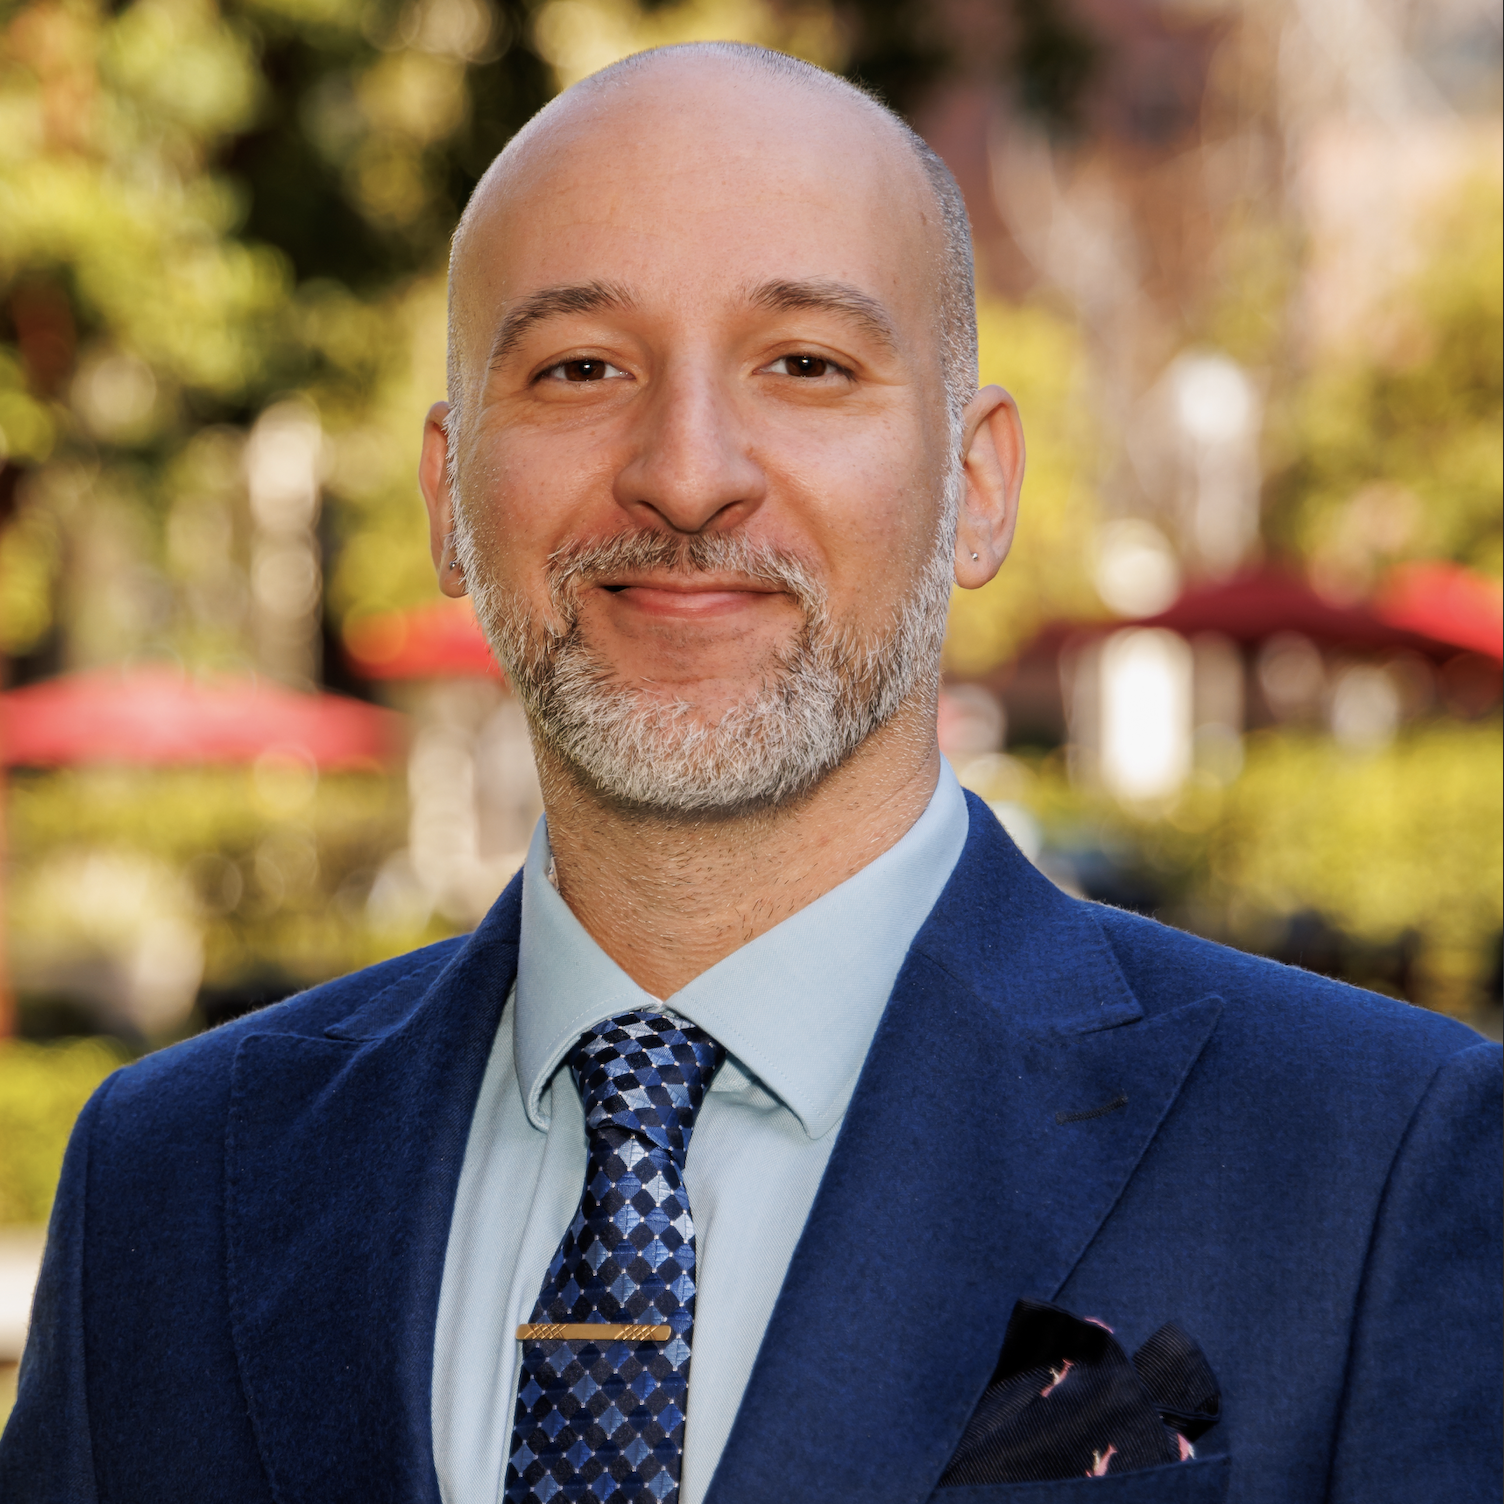
Robustness auditing of LLM agent simulations is a proposed direction. The talk topic and schedule will be agreed with the speaker.
Participation is subject to workshop acceptance and final scheduling.
Additional speakers and panelists will be announced as participation is confirmed.
Organizing Committee
Contribute to the Conversation
Methods, empirical studies, and well-supported arguments about agent failures, reliability, safety, and accountability are welcome.
Contributions may address an individual benchmark, detector, monitor, or diagnostic method. Ongoing work, negative results, and re-analyses are in scope.