
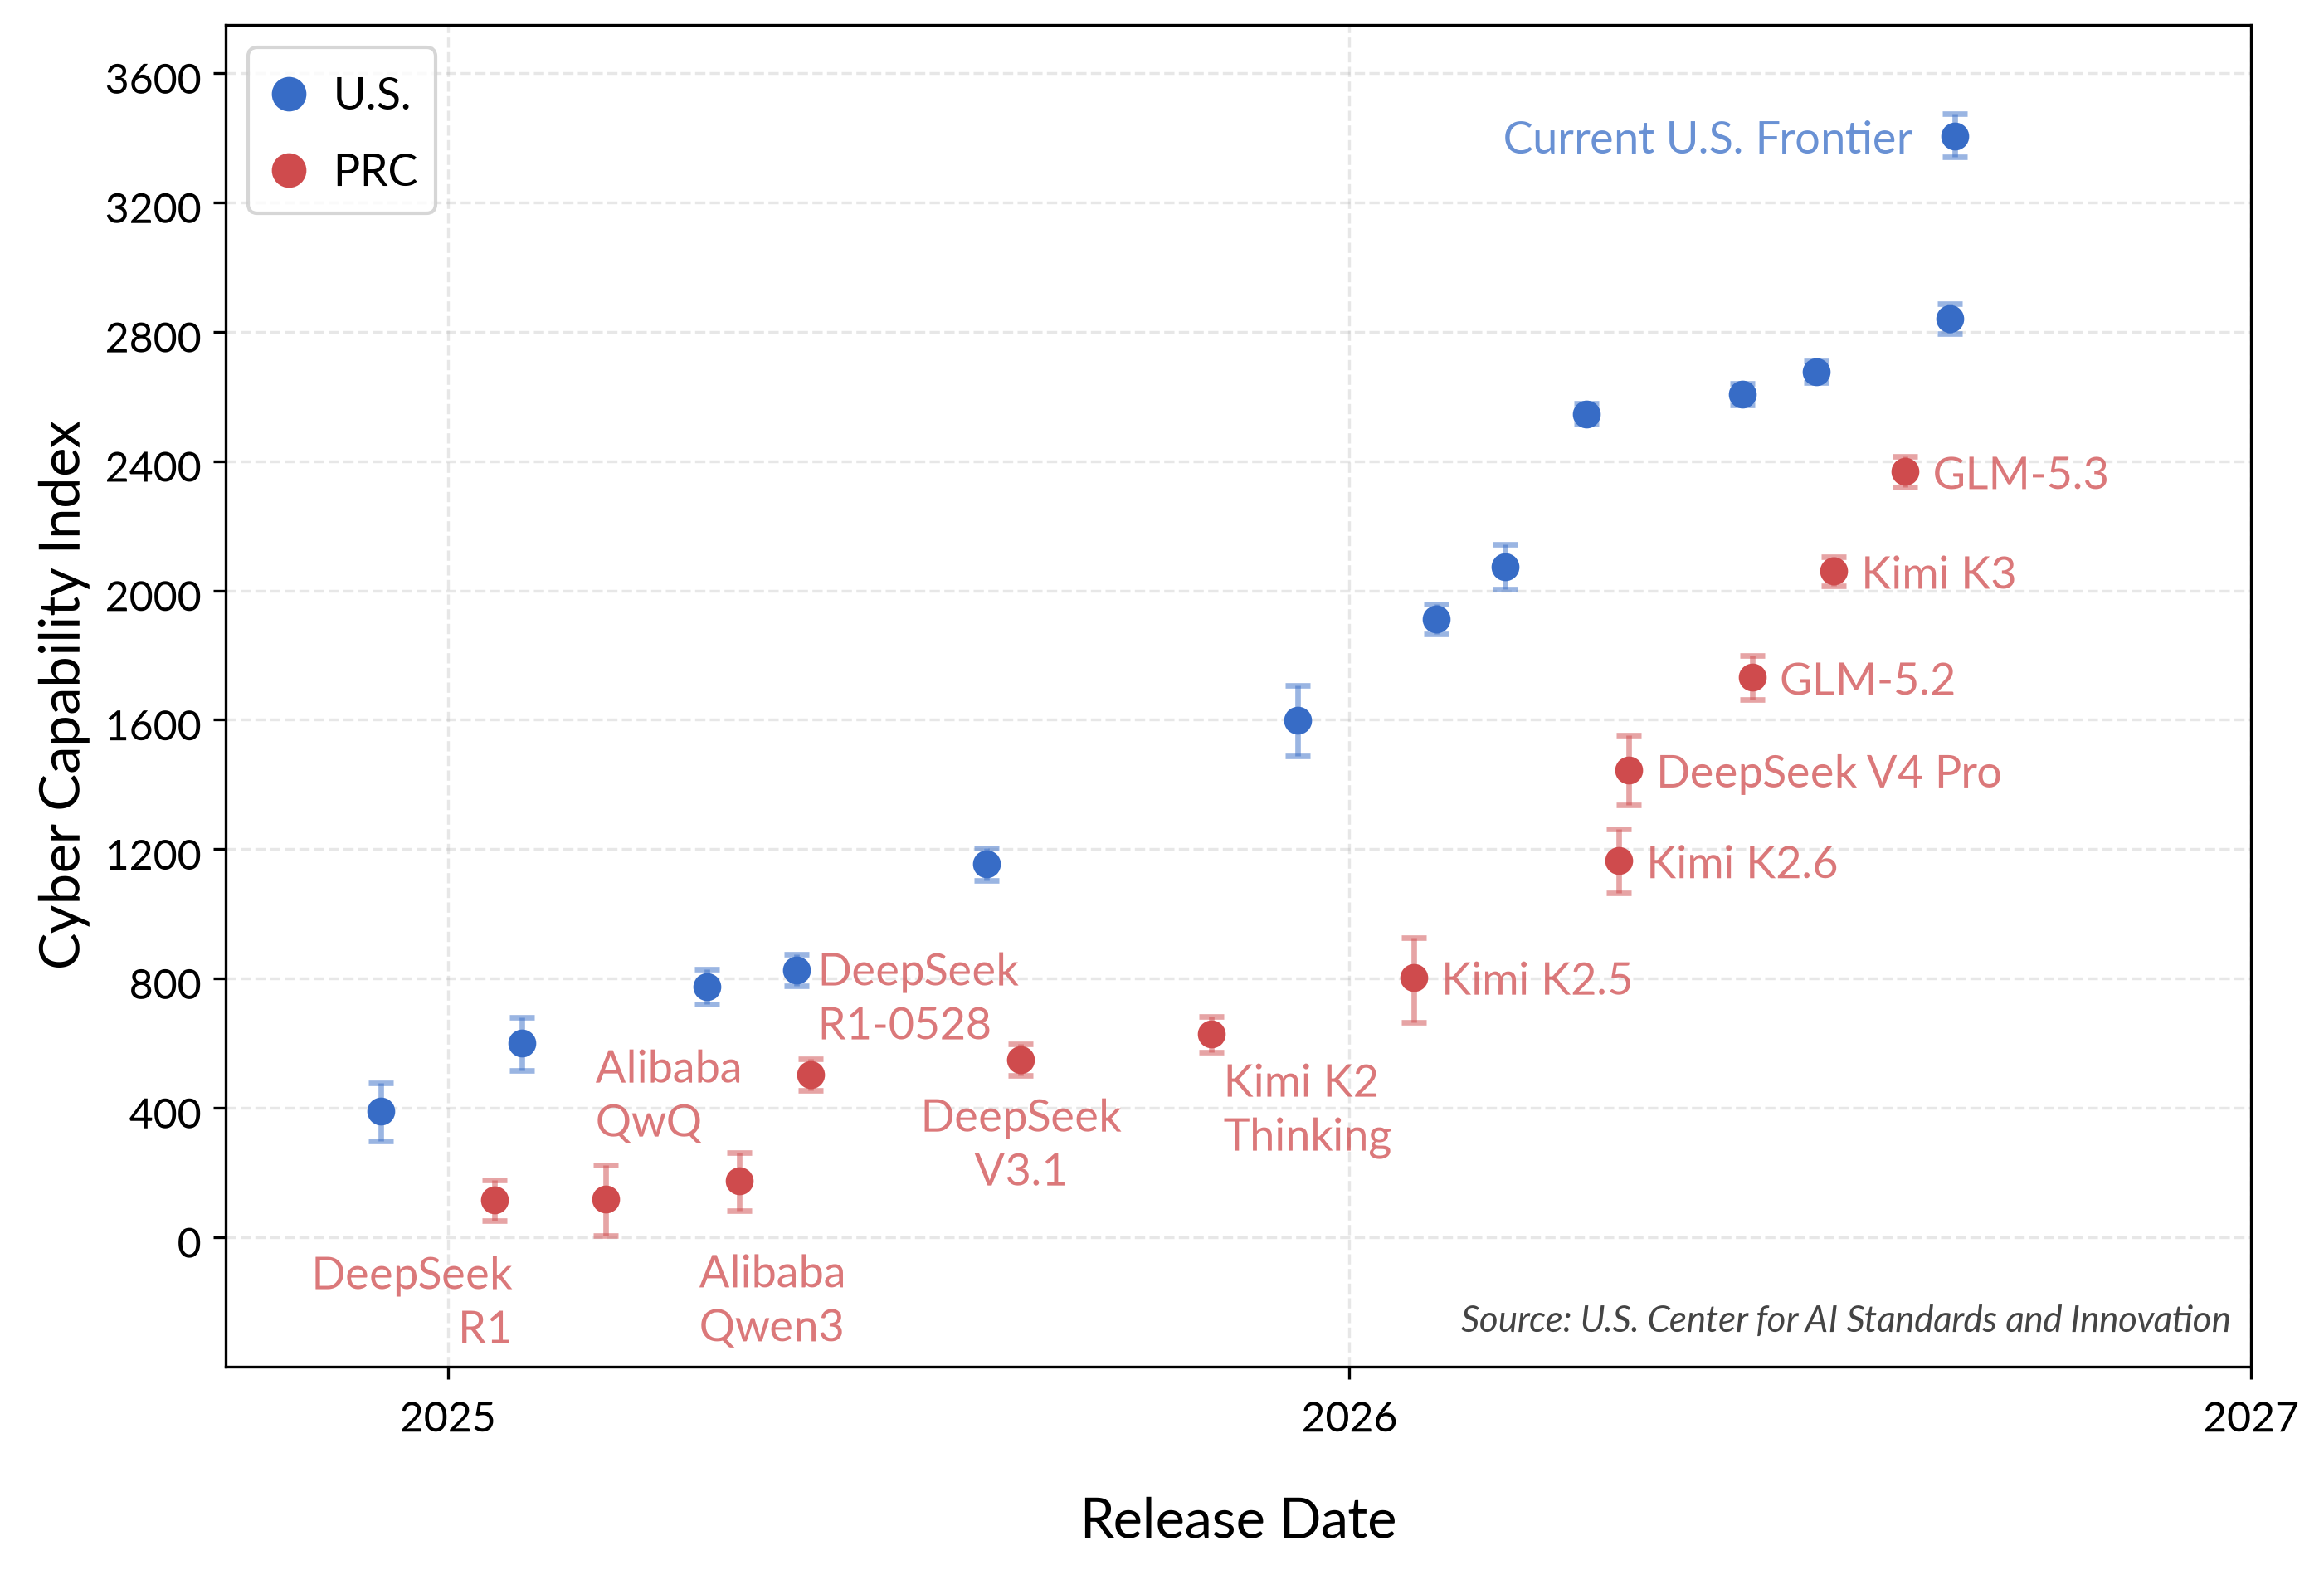
NIST's Center for AI Standards and Innovation (CAISI) published its GLM-5.3 cyber assessment on September 17. It compares performance on four vulnerability-discovery and exploit-development benchmarks.
Read the Evaluation Setup Alongside the Scores
CAISI ran models as agents with tools and benchmark-specific limits of 200 or 300 turns. Where applicable, U.S. models were evaluated with cyber safeguards disabled. The benchmark tables' U.S. frontier comparison takes the best score per benchmark, potentially from different models.
These conditions matter when interpreting the result: the assessment measures capability under its stated evaluation setup. It does not establish how an ordinary deployment with different safeguards, tools, or budgets would behave.
What Remains Hard to Reproduce
One of the four benchmarks, CAISI OSS-Fuzz, is private. The published methodology supports inspection of the setup, while full external reproduction remains limited.
Our editorial recommendation is to compare task definitions, tool access, safeguards, and run budgets before comparing headline scores. The evaluation-report guide provides a checklist for doing that.
Follow Audit Commons
Keep up with new reporting, practical guides, and resources in your feed reader.