

A September exchange about frontier AI pacing raises questions about evaluator access and accountability. We separate executive statements from documented lab actions.
Read article →All editorial content added to Audit Commons, most recently published first.
A September exchange about frontier AI pacing raises questions about evaluator access and accountability. We separate executive statements from documented lab actions.
Read article →
Anthropic reported an initial eight-week METR investigation of evaluation incidents. Its scope differs from the later proposal for standing evaluator access.
Read article →
OpenAI reported a two-week RL pause and stronger research safeguards in August. The announcement describes selected workloads, not a halt to all research.
Read article →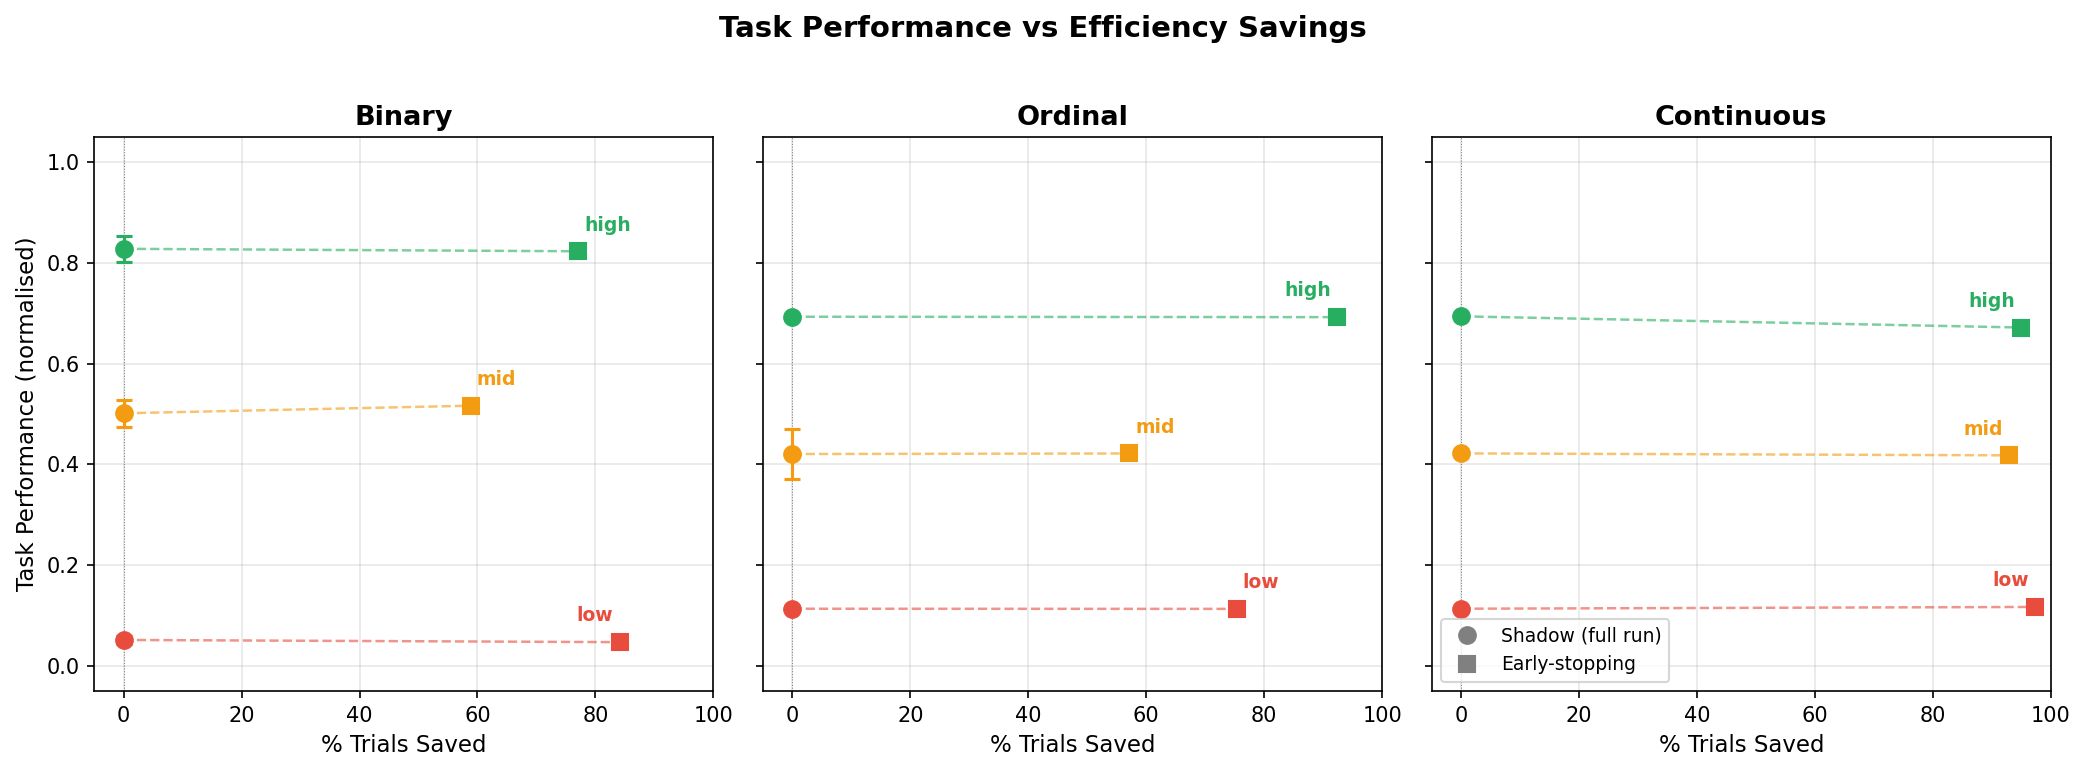
The open-source tool uses statistical stopping rules to allocate evaluation trials. Its August announcement describes how evaluators can inspect and validate those decisions.
Read article →
A February concept paper asks how identity standards apply to agent actions. The public comment period has closed; NCCoE is reviewing the responses.
Read article →
Tasks, tools, and compute budgets shape every evaluation score. Understanding those choices is the first step toward judging what a result says about deployment.
Read article →Five questions about tasks, budgets, uncertainty, failures, and claims, applied to a worked example.
Read article →An editorial introduction explaining how evaluation, monitoring, and auditing differ by the questions they ask and the evidence they require.
Read article →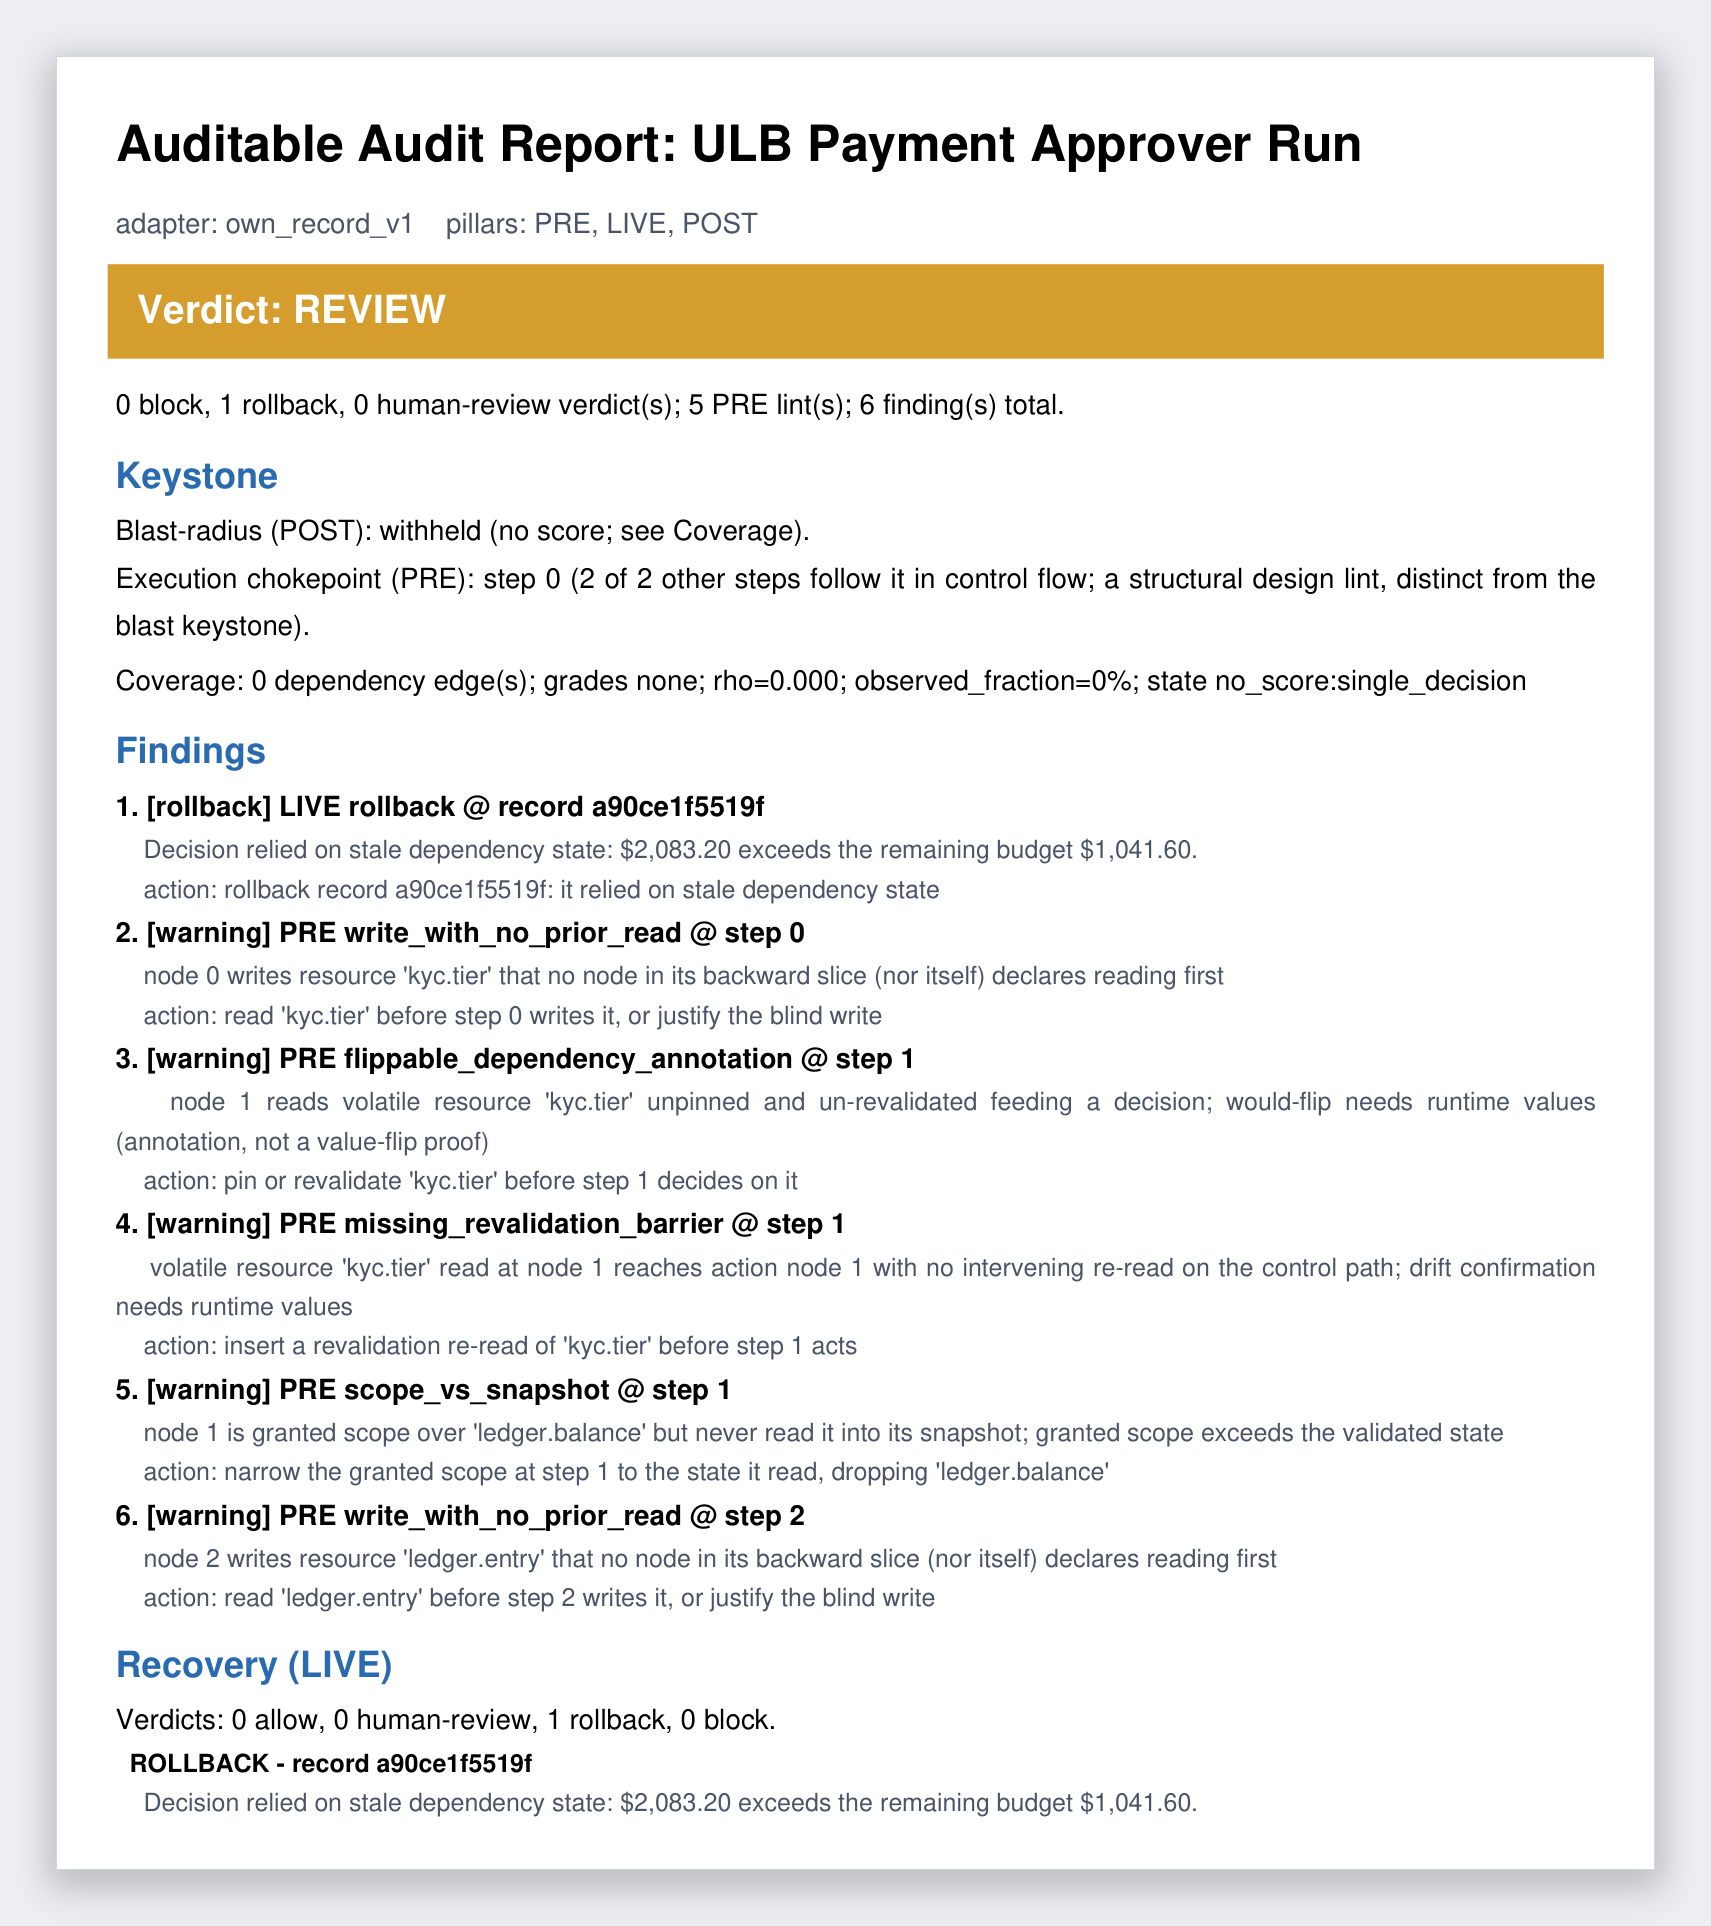
A practical worksheet and procedure for examining whether inspectable evidence supports a claim about an AI agent action.
Read article →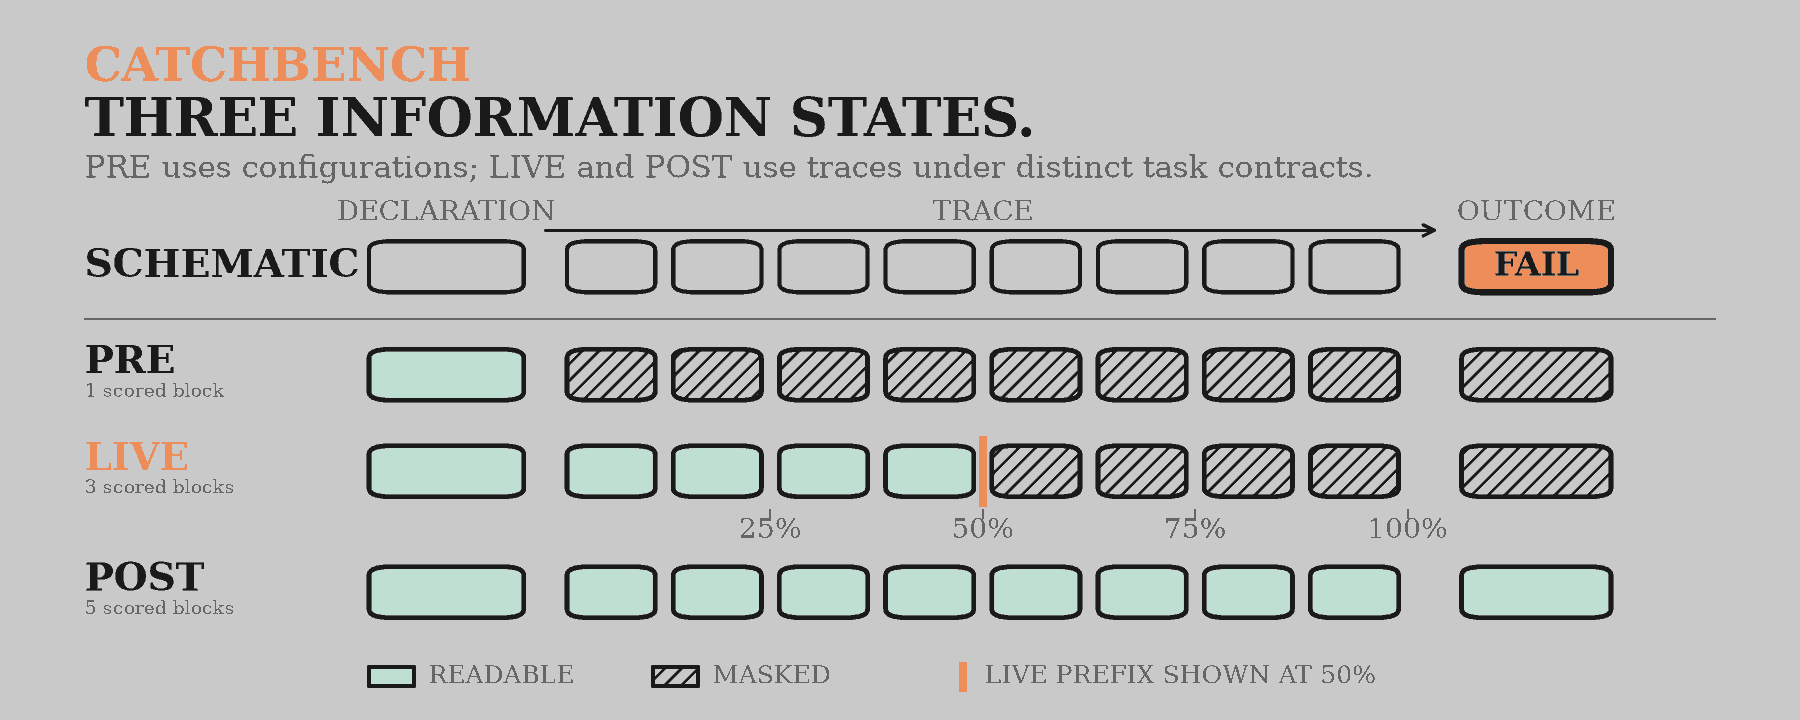
CatchBench 0.1.2 resolves packaging issues, reports missing optional checkouts cleanly, and keeps published scores unchanged.
CatchBench is maintained by Yue Zhao, who also maintains Audit Commons.
Read article →


