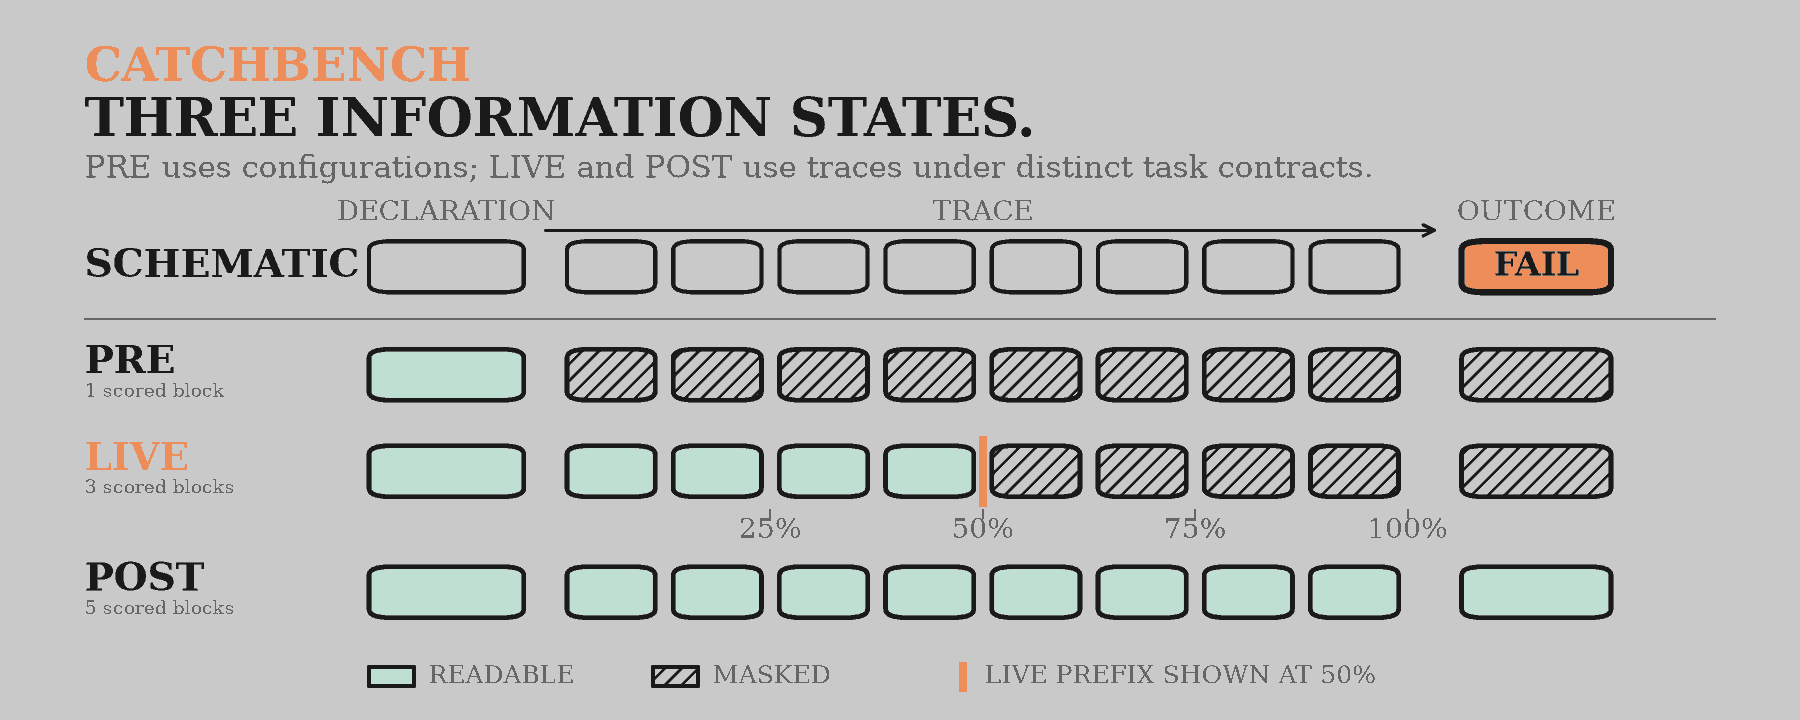
Four additions bring the catalog to 223 entries: a benchmark of research judgment built from human corrections to LLM research agents, a toolkit that checks agents' success claims against recorded evidence, a coding-agent safety benchmark, and a library that enforces action protocols at run time.
SciΠvot's first author submitted its entry, agent-claimcheck's author suggested it, and the list maintainer selected V³AST-Bench and Concordat. None of the four is affiliated with Audit Commons. The summaries follow each project's paper or repository. Catalog inclusion does not certify any method or result.
Read article →