What makes AI auditable?
An editorial introduction explaining how evaluation, monitoring, and auditing differ by the questions they ask and the evidence they require.
AI auditing
News, analysis & learning
Tasks, tools, and compute budgets shape every evaluation score. Understanding those choices is the first step toward judging what a result says about deployment.
Keep up with new reporting, practical guides, and resources in your feed reader.
An editorial introduction explaining how evaluation, monitoring, and auditing differ by the questions they ask and the evidence they require.
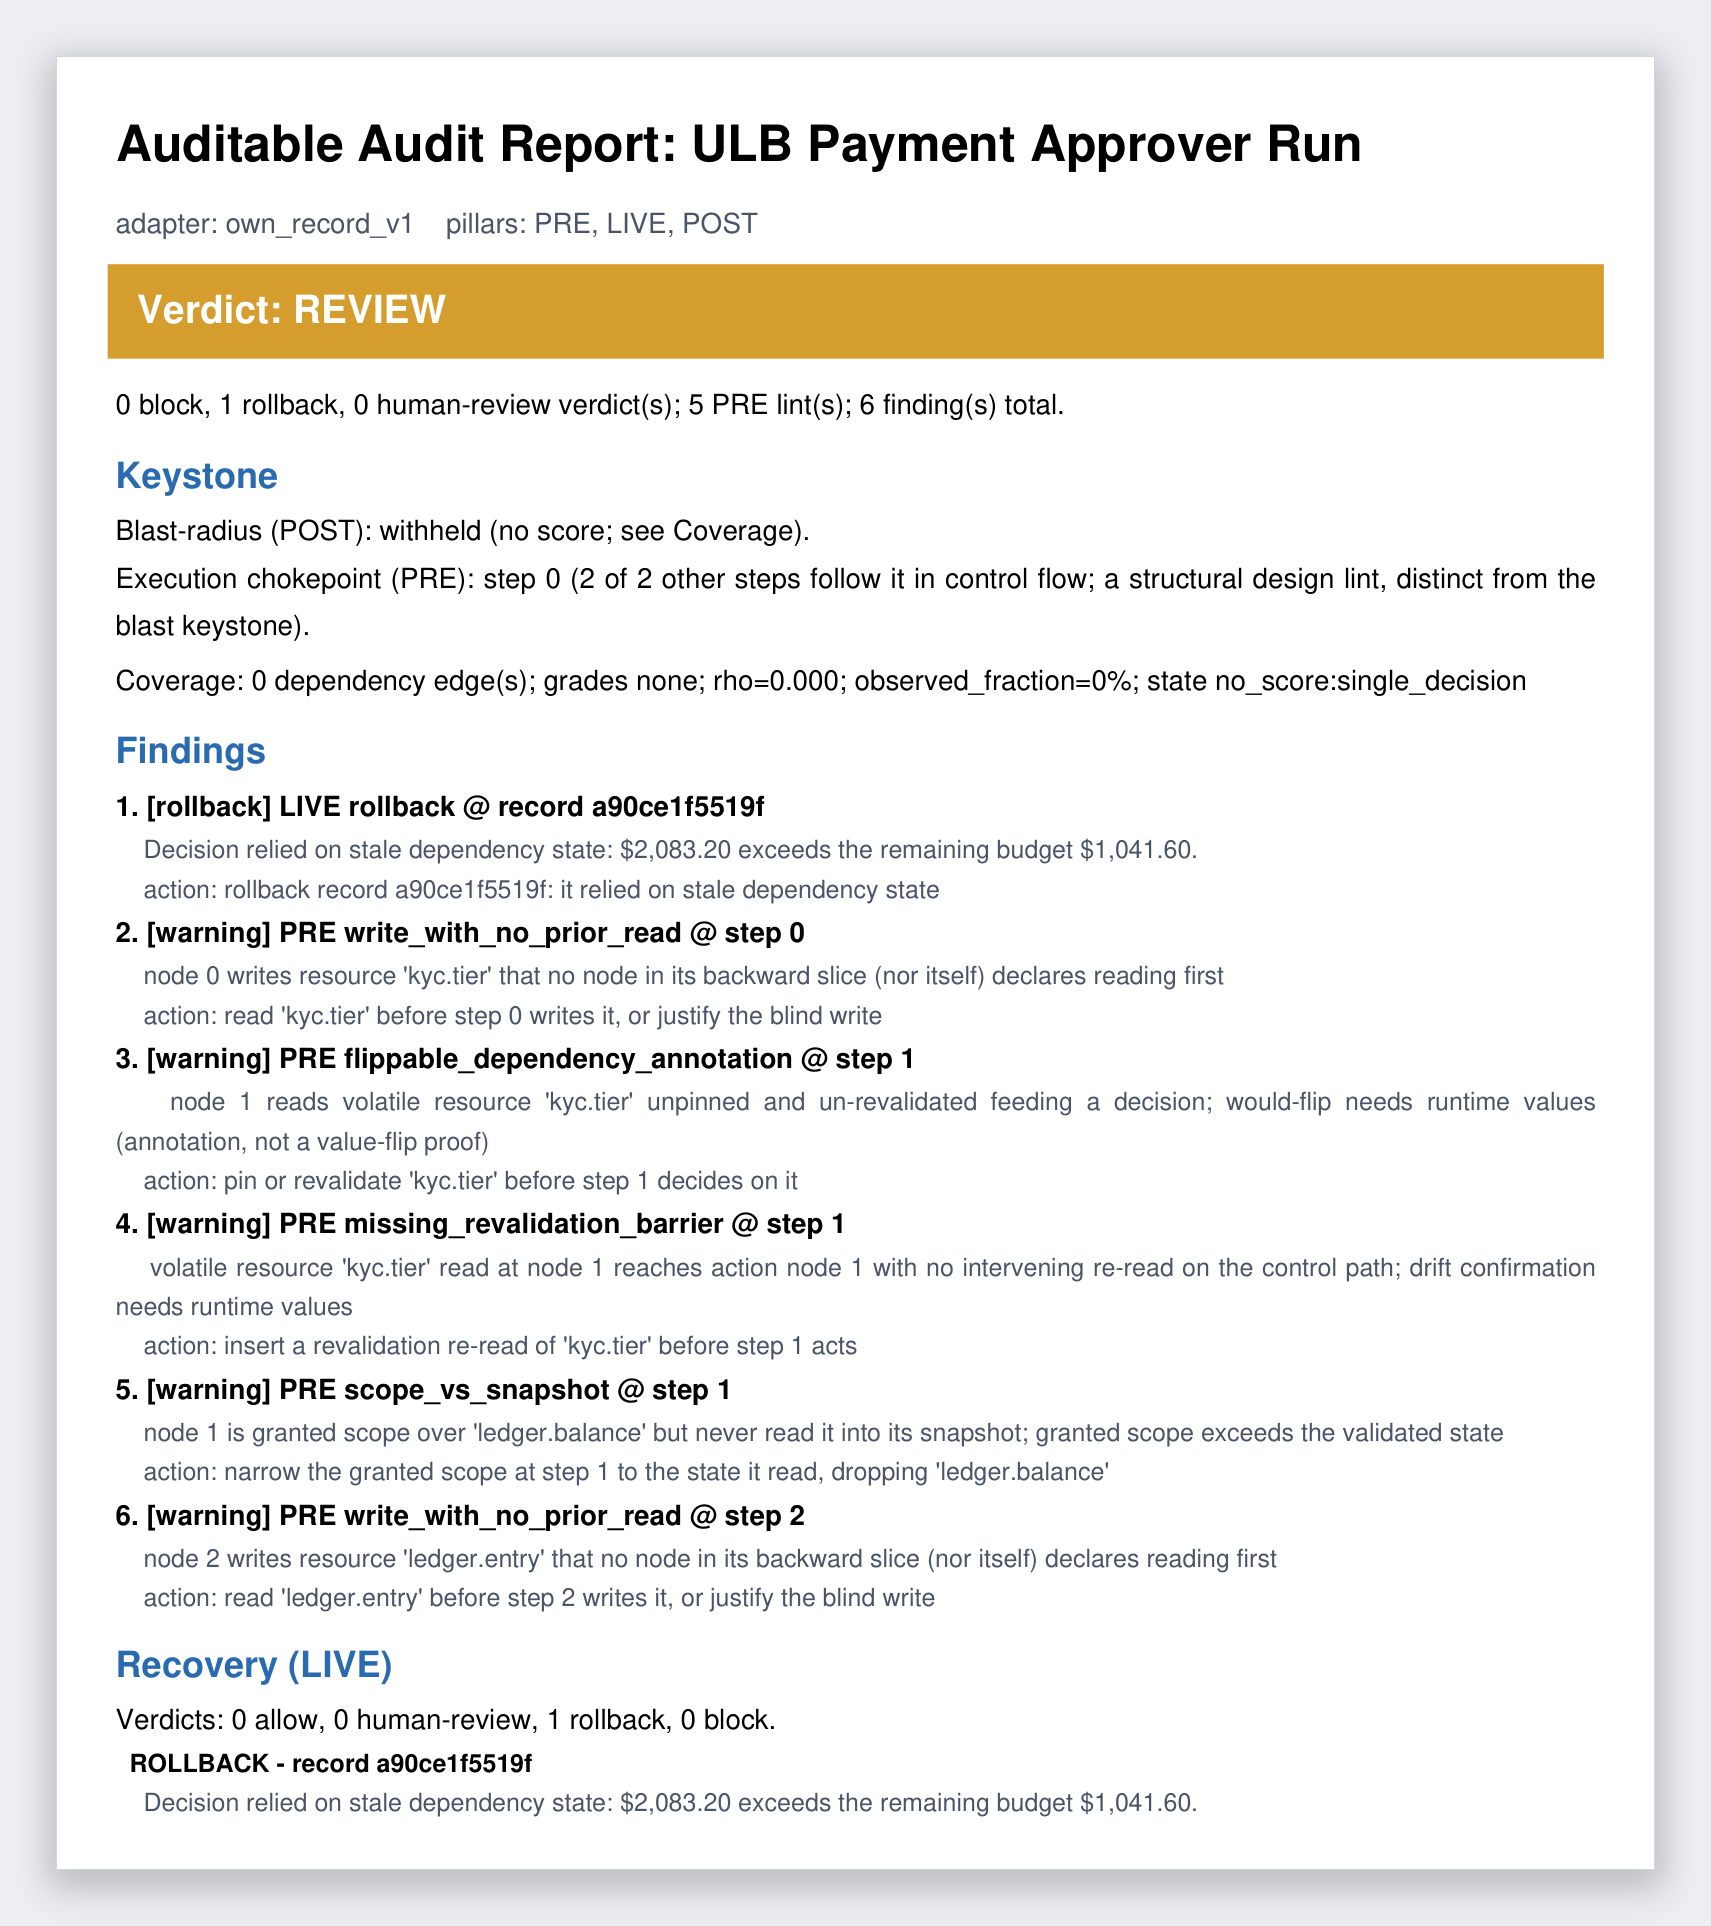
A practical worksheet and procedure for examining whether inspectable evidence supports a claim about an AI agent action.
Five questions about tasks, budgets, uncertainty, failures, and claims, applied to a worked example.